Case study
Two Years Idle, Running in Two Days: Recovering the Tote Lanes of an Automated Warehouse
Tote storage lanes idle for two years, running again in two days, then a week tracing outages across PROFINET, CANopen, AS-Interface and the IT boundary.
- Sector
- Warehousing and distribution
- Location
- Southern California
- Client
- Confidential
- Read
- 16 min
- 2 years → 2 daysTote storage lanes idle for two years, running again within two days on site
- 1 weekOn site, from first diagnosis to a prioritised risk register and plan
- 4 layersOutages traced across field, control, supervisory and IT layers
- 1 failureProtocol gateway failure handled mid-week, restored to named, connected and operational
Technologies Siemens S7 / TIA PortalPROFINET IOCANopenHMS Anybus X-gateway (PROFINET to CANopen)AS-Interface (Bihl+Wiedemann gateway)Pepperl+Fuchs AS-i I/OSEW-EURODRIVE drivesWindows 11 panel PCs
Executive Summary
An automated warehouse in Southern California had a section of its tote storage lanes out of service for two years. The lanes were part of the material flow, so their absence held back production every day they sat idle. Support from the equipment supplier, which the site was paying for, had not brought them back.
The site also had network outages it could not explain. Devices dropped off in different areas with no obvious pattern, each incident was handled locally, and nobody had looked at the architecture as a whole.
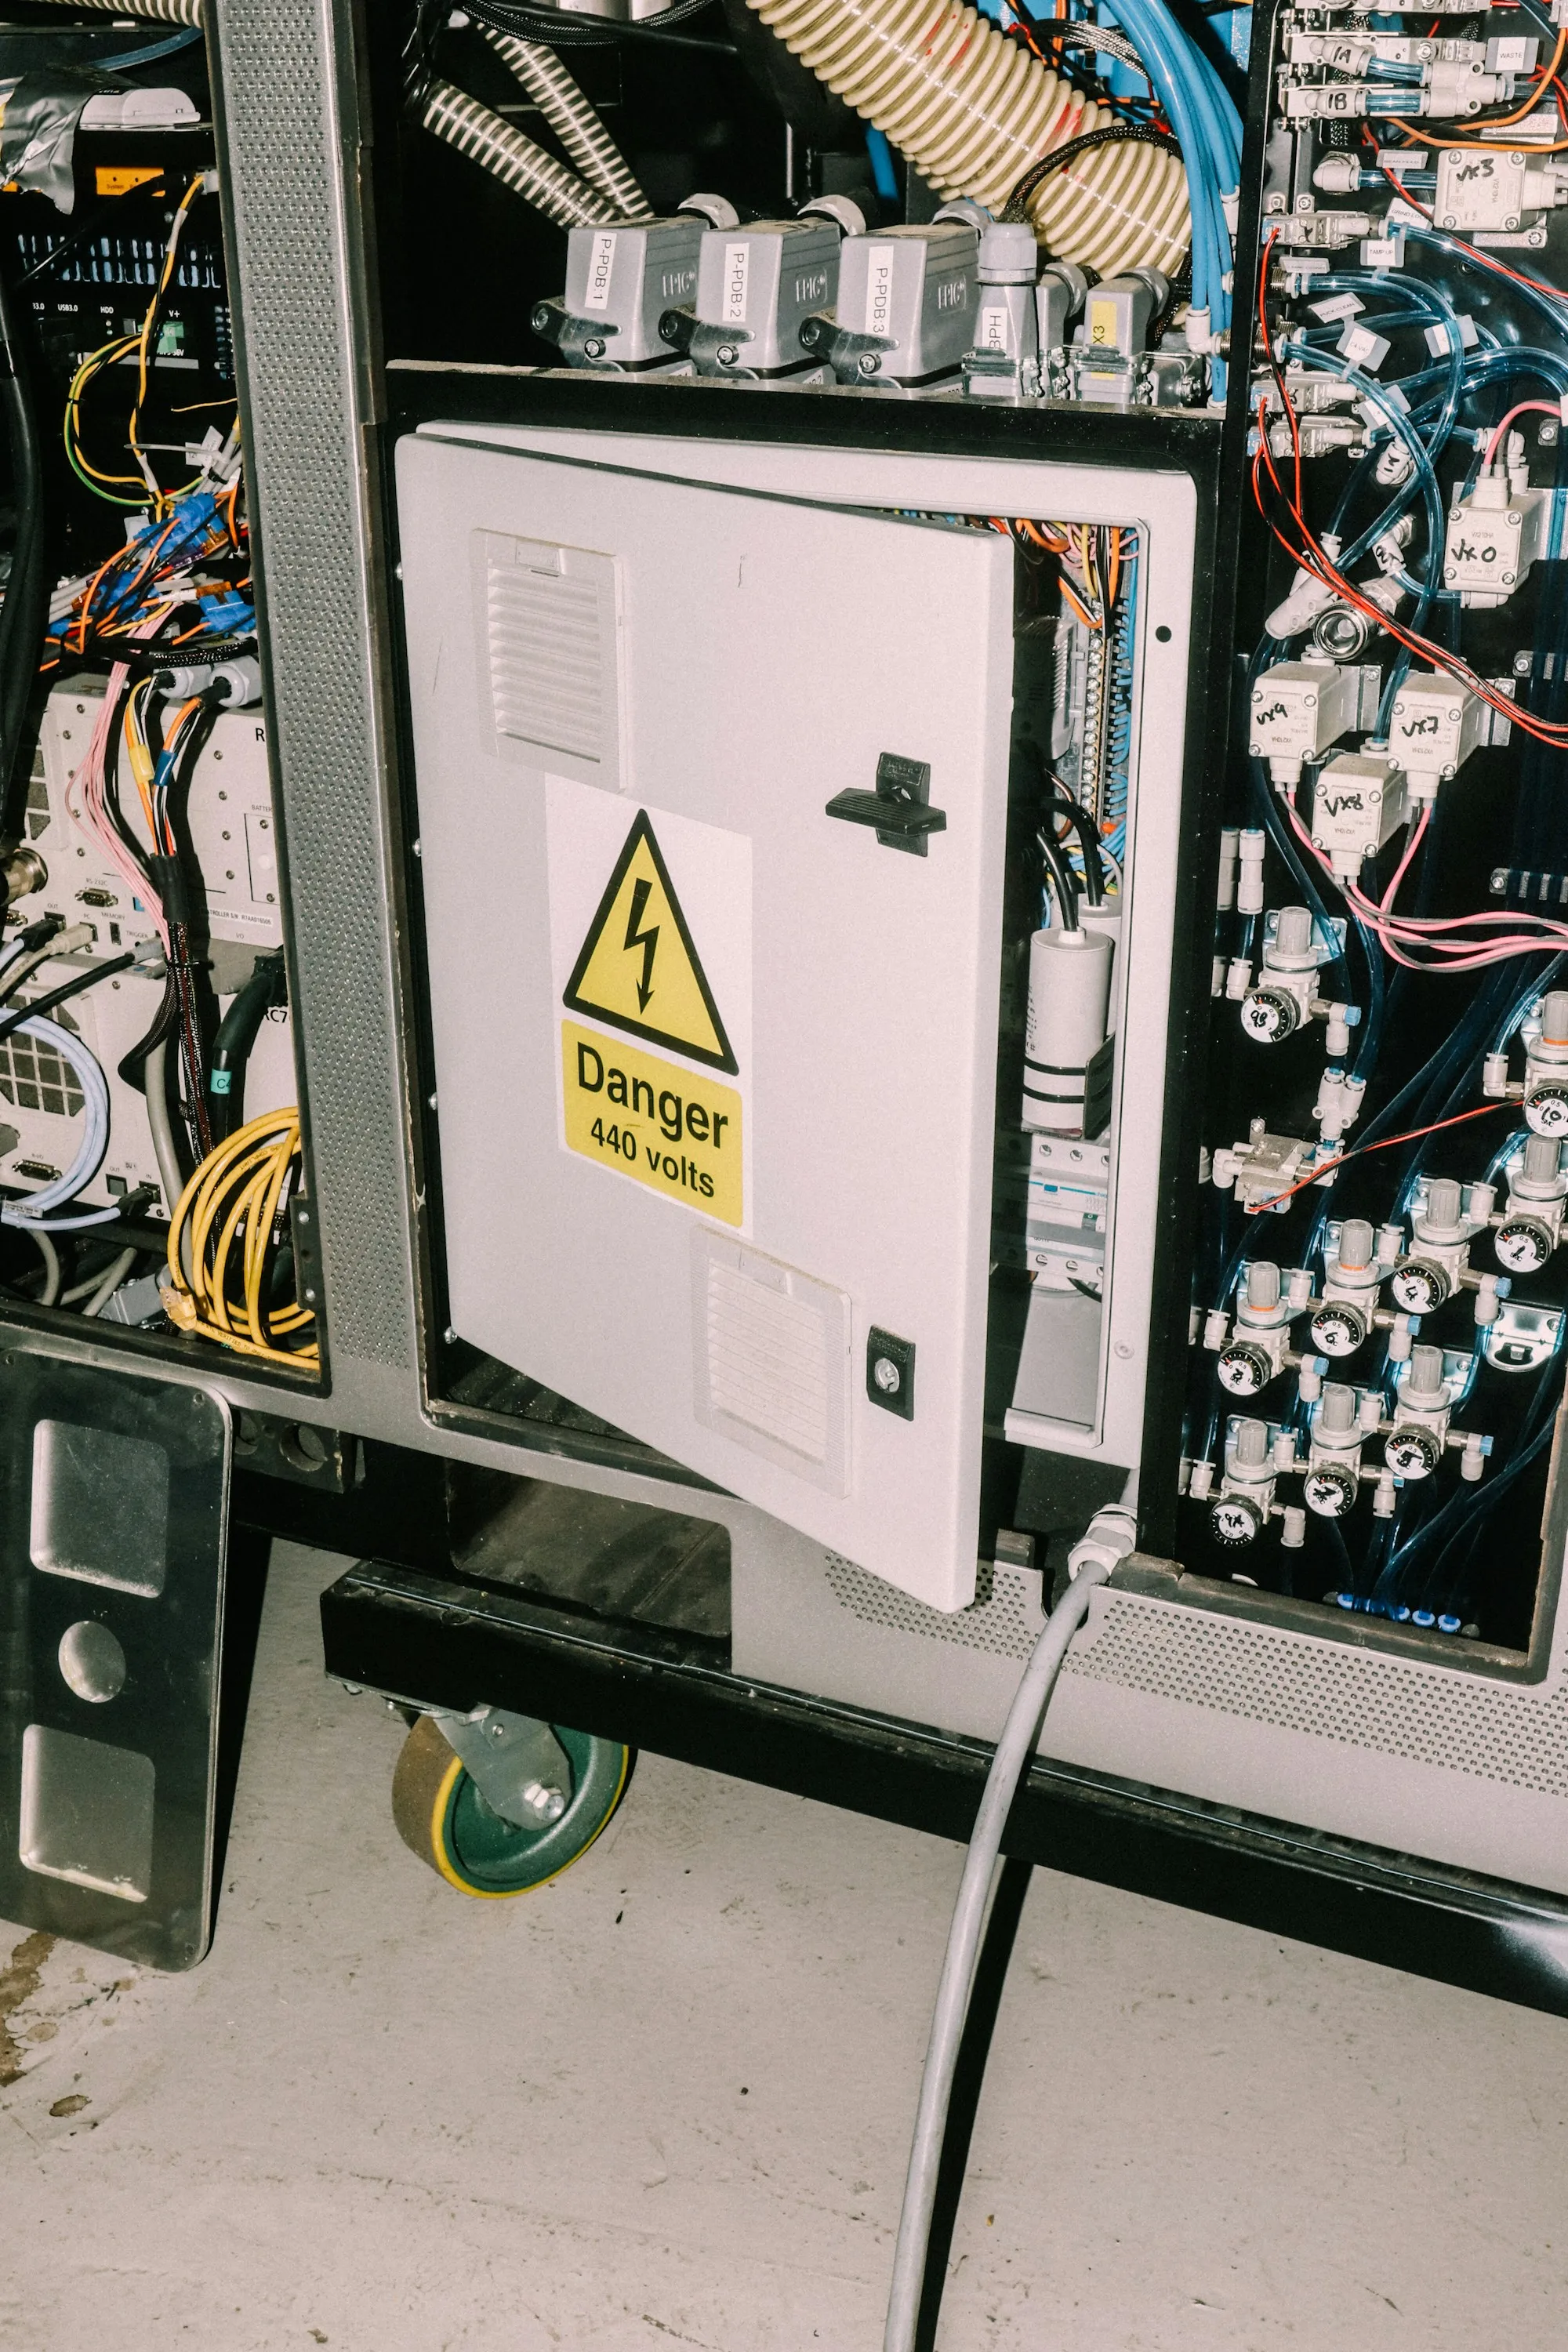
Joltek spent one week on site. The tote lanes were running again within two days. Getting there meant working through field hardware faults, miswired boards, misconfigured protocol gateways, wiring errors on the CANopen bus that runs to the drives, and errors in the operator interface. Mid-week, the gateway that translates between the Siemens PROFINET controller and the CANopen drives failed, and had to be brought back to a working, named and operational state.
The rest of the week traced the outages across all four layers of the plant: field networks, control, supervisory panel PCs, and the boundary with IT. The site left with the lanes producing, an AS-Interface gateway reconnected to its server, panel PC files backed up with technicians shown how to repeat it, and a risk register and plan, with a follow-up scheduled after the visit.
Impact Highlights
- Idle for two years, running in two days. Several tote storage lanes back in production within the first two days on site.
- A mid-week gateway failure handled. The PROFINET to CANopen gateway failed during the week and was restored to a named, connected and operational state.
- Outages traced across four layers. Field (CANopen, AS-Interface), control (PROFINET), supervisory (Windows 11 panel PCs) and the IT boundary.
- An IT-side root cause found. An AS-Interface gateway could not reach its server because of switch port configuration on the IT side.
- Recovery made possible. Panel PC files backed up, remote connectivity established, and site technicians shown how to do both.
- A risk register and a plan. Many risks identified across every layer, prioritised for the site, with a follow-up after the visit.
Site and Engagement Context
The site is an automated warehouse. Totes move through storage lanes driven by motors on a CANopen bus, controlled by Siemens PLCs over PROFINET, with operators working from Windows 11 panel PCs. Sensors and actuators in some areas sit on AS-Interface networks, connected upward through their own gateways. The equipment comes from Siemens and several other European vendors.
None of that is unusual. Like most sites, the architecture was built over several years by different people and suppliers. The pattern that matters is the gateways. Every place one network meets another, a gateway translates between them, and each gateway is configured in its own software, belongs to no single team, and is rarely documented. Gateways are where problems hide.
The Problem and the Risks
Two problems, one root pattern. The site brought us in for the idle lanes and the unexplained outages. They looked like separate problems. They turned out to share a cause: knowledge that sat in nobody’s job. The idle lanes crossed field hardware, board wiring, a bus, a protocol gateway, a PLC project and an operator interface. The outages crossed the plant’s own networks and the IT team’s switches. Each piece belonged to someone, and the whole belonged to no one.
The cost of leaving it. Lanes that hold totes are capacity. Several of them out of service for two years is capacity the site paid for and could not use, and production was working around them every day. The outages carried a different risk: intermittent faults that are handled locally keep returning, and each return costs time and confidence in the system.
For context, Siemens estimates that unplanned downtime costs the world’s 500 largest companies about 11 percent of their revenue, or US$1.4 trillion a year. Those are industry figures, not this site’s numbers. They explain why an asset that “doesn’t work” is worth a week of focused attention.
Why two years. No single fault on the lanes was hard. What made the problem durable was that it crossed boundaries between vendors, tools and teams, and the supplier support the site was paying for did not close it. That is how a solvable problem becomes “the machine that doesn’t work”: everyone knows about it, and nobody owns it.
Objectives and Success Criteria
| # | Objective | Success criterion |
|---|---|---|
| 1 | Return the idle tote lanes to production | Lanes running and moving totes, accepted by the site |
| 2 | Find why devices drop off the network | A root cause per incident, not a reset |
| 3 | Restore the AS-Interface gateway’s link to its server | Gateway reporting to the server again |
| 4 | Make the panel PCs recoverable | Files backed up, a remote path established, technicians able to repeat it |
| 5 | Leave the site able to act without us | A risk register and a plan, with a follow-up after the visit |
Baseline Assessment
The rule for the week: read the equipment before touching the laptop. Status LEDs, fault registers and nameplates usually say more in five minutes than an hour of guessing does. We worked from the device outward, one layer at a time.
What we found on the lanes was not one failure but several stacked on each other:
| Layer | Finding |
|---|---|
| Field hardware | Faulty field devices on the lanes |
| Boards and wiring | Miswired boards |
| CANopen bus | Wiring errors on the bus running to the drives, and the connection to the bus master |
| Protocol gateways | Misconfigured gateways between the field networks and PROFINET |
| Operator interface | Errors on the HMI |
What was surprising was how much of it was configuration and wiring rather than failed hardware. Default or missing names, wrong ports and miswired connections caused more of the trouble than parts that had actually broken.
Strategy and Design Decisions
Lanes first. The idle lanes held the most value, so they came first. The network investigation could run once the lanes were producing, and some of what we learned on the lanes would inform it.
Fix in layer order, and confirm each layer on its own. A device can be powered and still be invisible. It can be named and still be unconnected. It can be connected and still exchange no data. We treated each of those as a separate state to prove, rather than assuming that a healthy indicator at one layer meant the layers above it were fine.
One owner per setting. Where two tools can write the same value, such as a device name that the gateway tool and the PLC project can both set, one will eventually overwrite the other and the fault will return. We chose a single place to own each setting and recorded it.
Implementation
| Days | Focus | What happened |
|---|---|---|
| 1 to 2 | Tote lanes | Field hardware, board wiring, CANopen bus wiring and the bus master connection, gateway configuration and HMI errors worked through until the lanes ran |
| 3 to 4 | Network outages | Each outage traced layer by layer: physical, addressing, device identity, controller connection, and the IT boundary |
| Mid-week | Gateway failure | The PROFINET to CANopen gateway failed and was restored to a named, connected and operational state |
| 5 | Baseline and handover | Panel PC backups, remote connectivity, technician coaching, the risk register and the plan |
The PROFINET to CANopen gateway. An HMS Anybus X-gateway sits between the Siemens controller and the CANopen side, translating between the two. Its Module Status LED flashed red three times, which on this gateway’s PROFINET interface means the station name or IP address is not set. The station name was blank. PROFINET controllers find their devices by station name, using the Discovery and Configuration Protocol (DCP), not by IP address, so a device without the right name is invisible to the PLC even when it is powered, wired and otherwise healthy.
We set the name from TIA Portal to match the name already in the PLC project, exactly. PROFINET names follow strict rules on lowercase and special characters, and TIA Portal quietly converts a name it does not allow into a different “converted” name, which is a reliable way to end up with two names that look alike and do not match.
With the name set, Module Status went green and Communication Status stayed off. The device was healthy and named but not yet owned by the controller. Assigning it to the PLC’s PROFINET IO system and downloading the hardware configuration brought Communication Status on. Data still did not move to the CANopen side until the controller sent the OPERATIONAL command in the gateway’s control word. This gateway starts in a pre-operational state and exchanges no I/O until it is told to.
The CANopen bus and the drives. Drives on the lanes were tripping, including an SEW-EURODRIVE drive reporting Error 14, an encoder fault code. Rather than resetting it again, we treated the trips as a pattern. The cause was on the bus itself: the connection to the master of that network chain, and several wiring faults along the bus across drives and I/O cards. A nearby Pepperl+Fuchs AS-Interface I/O module read healthy on inspection, with communication good, auxiliary power good and no output faults, which let us rule it out and keep the search on the bus.
Challenges and How They Were Resolved
| Challenge | Impact | Resolution |
|---|---|---|
| The PROFINET to CANopen gateway failed during the week | The bridge between the controller and the lane drives was down after the lanes had been brought back | Restored step by step through the four states: station name, IO system assignment and hardware download, then the OPERATIONAL command |
| Several faults on different layers of the lanes | No single fix brings the lanes back on its own, so progress is hard to see | Worked layer by layer and confirmed each layer independently before moving up |
| An AS-Interface gateway showing an Ethernet error with no connection, while power and safety LEDs were green and the port showed link activity | The device looked alive and cabled but was not reporting to its server | Checked in order: address and protocol on the gateway’s display, the port in use, ping and browser checks from the same subnet, a duplicate-address scan, the receiving side’s connection status. The cause was switch port configuration on the IT side, not the gateway |
| Devices that discovery tools could see but nothing could reach | Misleading evidence that a device was “on the network” | Discovery tools such as PROFINET DCP scans and HMS IPconfig work at Layer 2 and see devices in other IP subnets on the same switch or VLAN. A ping, a browser or a controller connection needs a real route. We tested reachability, not visibility |
| Panel PCs with no recovery path | A failed panel would mean rebuilding an operator station from scratch | Files backed up, remote connectivity worked out, and technicians shown how to repeat it. The remaining recovery steps went into the plan |
Results and Impact
| Objective | Result | Basis |
|---|---|---|
| Idle tote lanes back in production | Running within two days of arriving on site | On-site record of the engagement |
| Root causes for the outages | Traced across field, control, supervisory and IT layers; the AS-Interface gateway’s root cause found on the IT side | Fault-by-fault investigation during days 3 to 4 |
| AS-Interface gateway reporting | Restored to its server once the port configuration was corrected | Gateway reconnected on site |
| Panel PC recovery | Partly in place: files backed up, remote connectivity established, technicians coached | Completed on site; remainder in the plan |
| Site able to act without us | A risk register and a plan, with a follow-up after the visit | Delivered at the end of the week |
The bigger finding was the size of the remaining work. The week surfaced many risks across every layer of the site, from field wiring to the IT boundary. That is common: Dragos reports poor separation between IT and OT networks in 81 percent of its OT service engagements. The risk register puts the site’s own list in order, so the next round of work goes to the risks that matter most for production.
What we recommended for the panel PCs goes beyond files. Live image-level backups with bare-metal restore, so a panel can be captured without stopping production. BitLocker recovery keys saved before any imaging, since Windows 11 can turn device encryption on automatically once a Microsoft or Entra account signs in. A record of any node-locked runtime licences, which have to be moved deliberately when a panel is replaced. And a tested restore before any backup counts as done.
Lessons Learned
- Read the device first. LEDs and fault registers narrowed each problem to one cause in minutes.
- Names, addresses and ports cause most network failures. Blank names, wrong ports and miswired connections caused more trouble than broken hardware.
- One owner per setting. When two tools can write the same value, the fault eventually comes back.
- Healthy is not the same as connected. Power, identity, connection and data exchange each have to be confirmed on their own.
- Look across the IT boundary early. The AS-Interface gateway’s fault was not in the gateway or the plant network at all. The plant and IT teams each held half of the answer.
- Fix it once, then write it down. A fix nobody can repeat is only a delay, which is why the week ended with technicians doing the backups themselves and a risk register in the site’s hands.
If you have equipment that has been “down for good”, or outages nobody can pin down, this is the kind of work we do in a plant systems assessment and an OT network assessment. We also provide commissioning support to bring idle or new equipment up to rate. For the technical background, see our notes on OT network architecture and controls.
Technical References
- HMS Anybus X-gateway PROFINET IO interface, LED indications (manual HMSI-168-91): https://www.manualslib.com/manual/1391568/Hms-Ab7307.html?page=12
- Siemens TIA Portal, PROFINET device names and converted names: https://docs.tia.siemens.cloud/r/it-it/v20/simotion-scout-tia-device-configuration/configuring-communication/profinet-io/device-settings-on-the-profinet-io
- Siemens S7-1500 Communication Function Manual (DCP is Layer 2 and not routable): https://cache.industry.siemens.com/dl/files/925/59192925/att_61992/v1/s71500_communication_function_manual_en-US_en-US.pdf
- Bihl+Wiedemann, replacing a gateway and its chip card: https://bihl-wiedemann.de/pl/support/replacing-a-defective-device-without-chip-card-profinet
- SEW-EURODRIVE fault documentation (encoder fault F14): https://download.sew-eurodrive.com/download/pdf/11697415_G12.pdf
- Pepperl+Fuchs AS-Interface I/O module LED indications: https://files.pepperl-fuchs.com/webcat/navi/productInfo/pds/129640_eng.pdf
- Microsoft, back up your BitLocker recovery key: https://support.microsoft.com/en-us/windows/security/encryption/back-up-your-bitlocker-recovery-key
- Microsoft, Volume Shadow Copy Service (live backups of running Windows systems): https://learn.microsoft.com/en-us/windows-server/storage/file-server/volume-shadow-copy-service
- Siemens, The True Cost of Downtime 2024: https://assets.new.siemens.com/siemens/assets/api/uuid:1b43afb5-2d07-47f7-9eb7-893fe7d0bc59/TCOD-2024_original.pdf
- Dragos, OT cybersecurity lessons learned from the frontlines: https://www.dragos.com/blog/ot-cybersecurity-lessons-learned-frontlines